CVE-2026-111497: Patch the Brotli Bug on Ubuntu
CVE-2026-111497 is a Brotli decoder bug that's already being exploited. Which Ubuntu packages fix it, what apt won't fix, and how to check you're patched.
Insights on monitoring, incident management, and keeping your infrastructure reliable.

Real user monitoring measures what your visitors actually experienced. Synthetic monitoring tests what happens when nobody is watching. Here's how the two differ, where each one lies to you, and why most teams end up running both.

What each incident severity level means, how to classify an incident fast, the escalation ladder that follows, and why five levels is usually two too many.

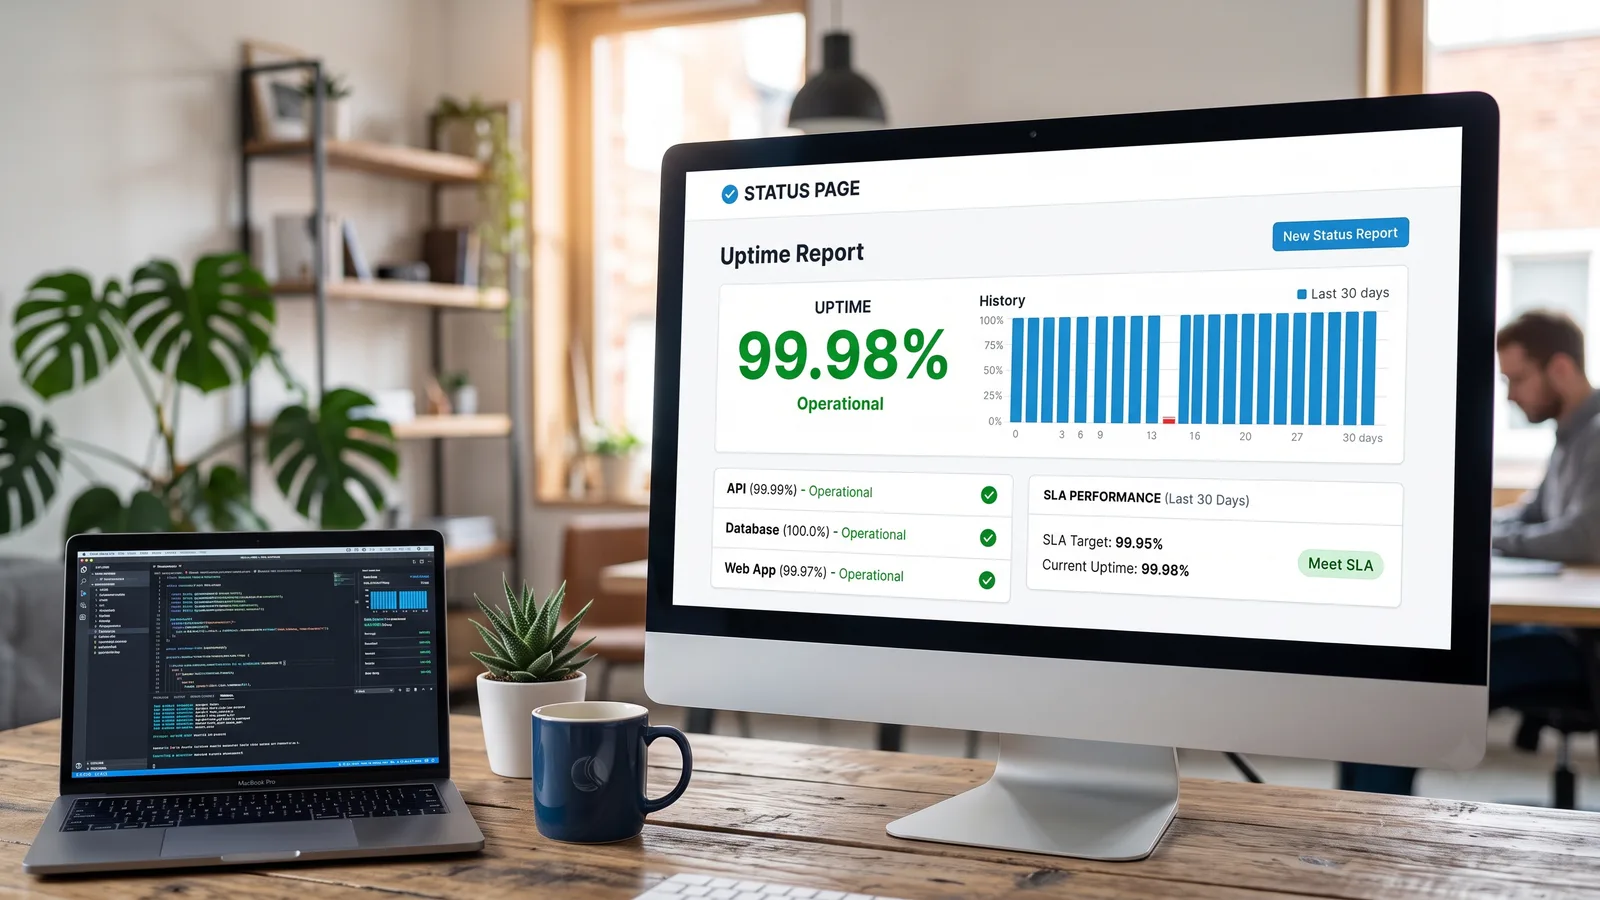
Publishing an uptime number customers will actually believe: what to disclose, how to handle maintenance and partial outages, and how to report a month you missed without losing the account.

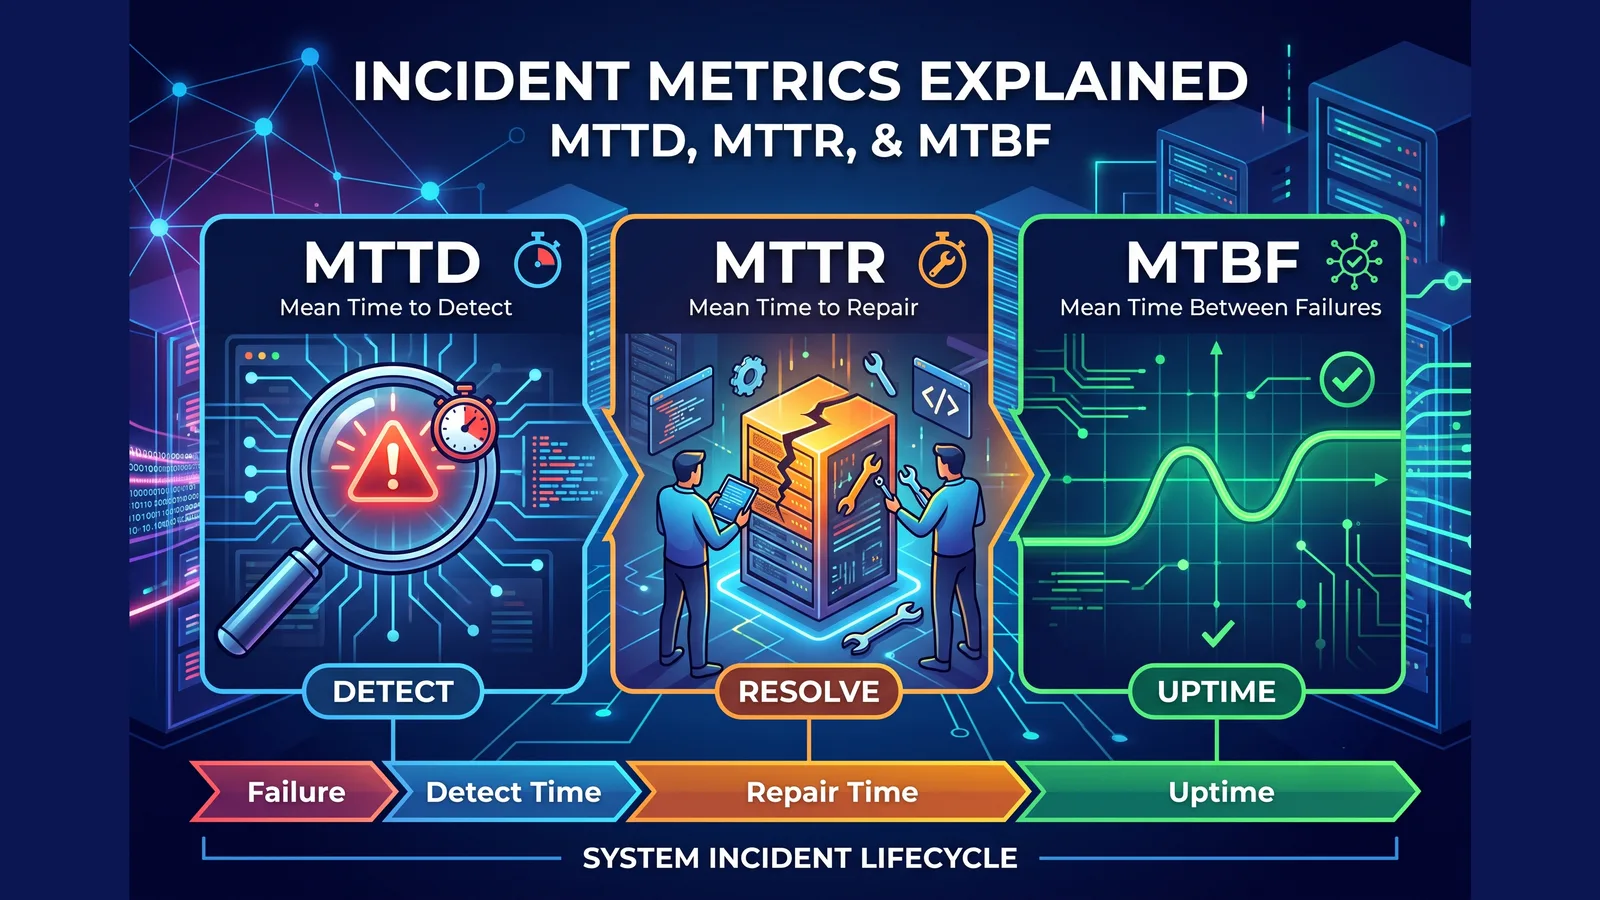
The five incident metrics teams actually track, the formulas behind them, which one to fix first, and the averaging mistake that makes all of them lie to you.

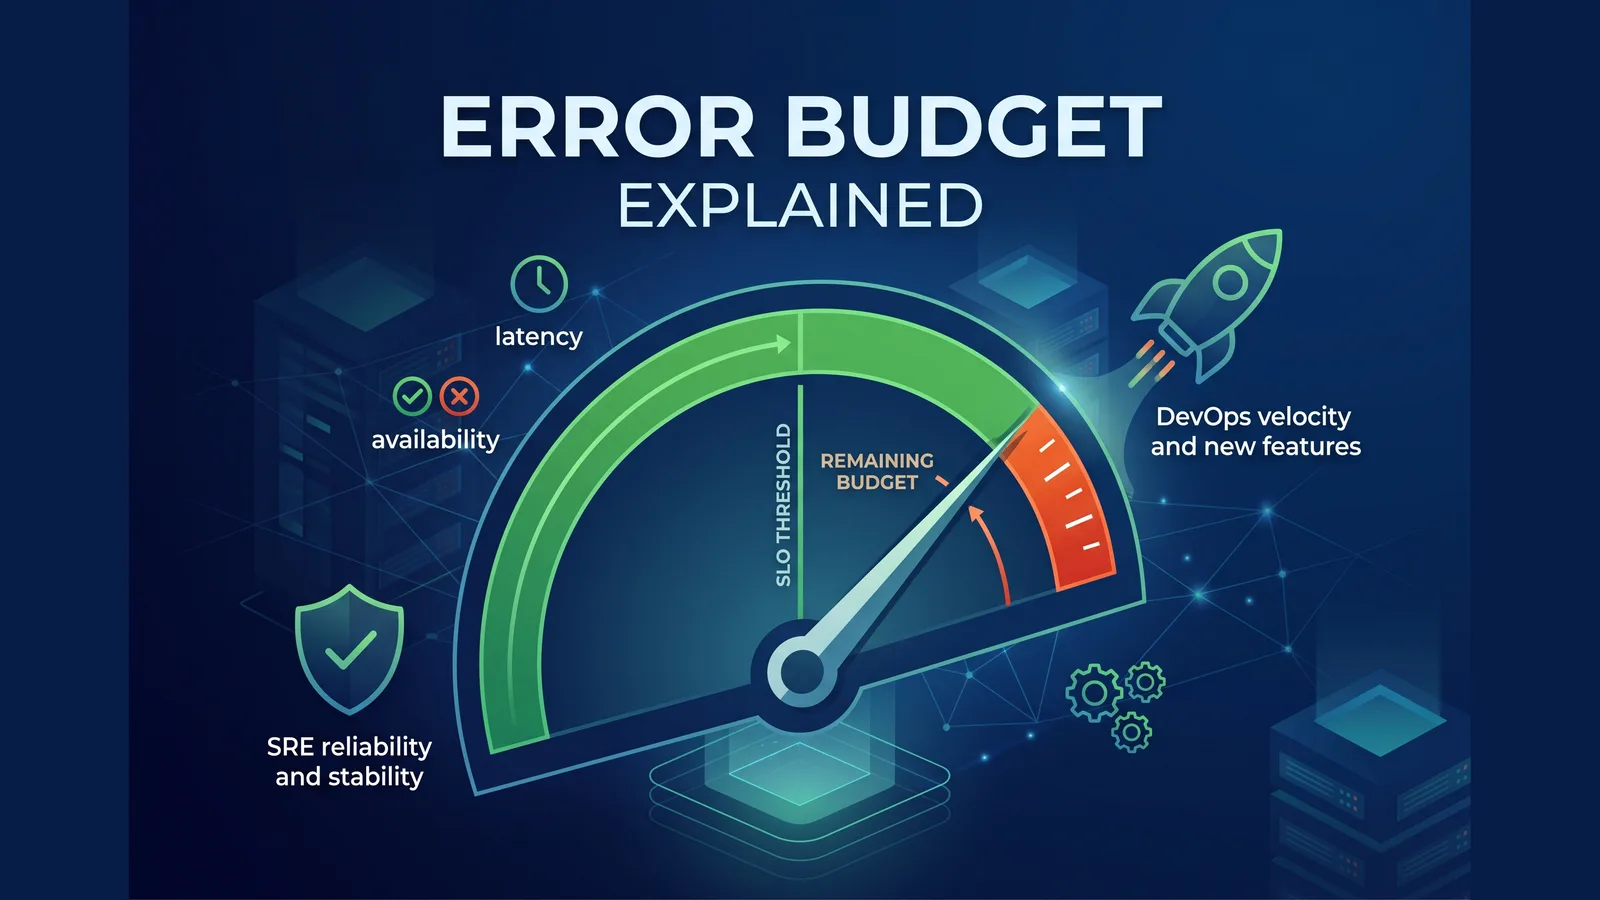
An error budget turns your allowed downtime into a resource you spend on purpose. Here's how to calculate one, track burn rate, and attach a policy that actually changes behaviour when the budget runs out.

An open standard that lets AI assistants talk to your systems through one interface. How MCP works — hosts, clients, servers, tools, transports — and why ops teams care.

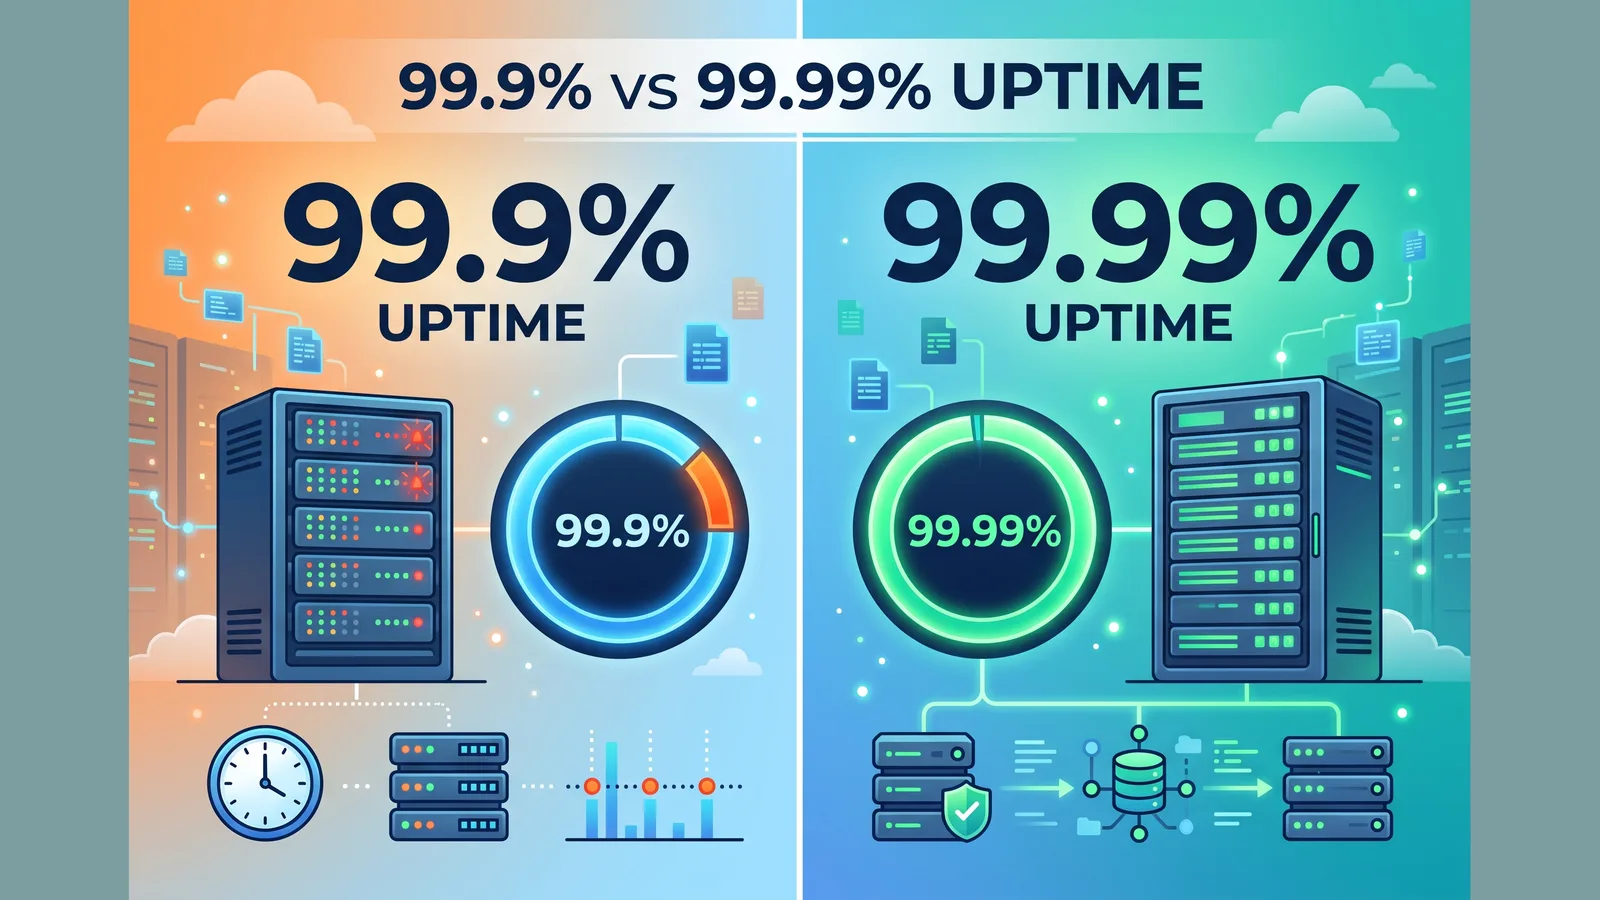
What each uptime percentage allows in minutes per year, month, week, and day — plus how the number is calculated, why the measurement window matters more than the target, and what each tier actually costs to hit.

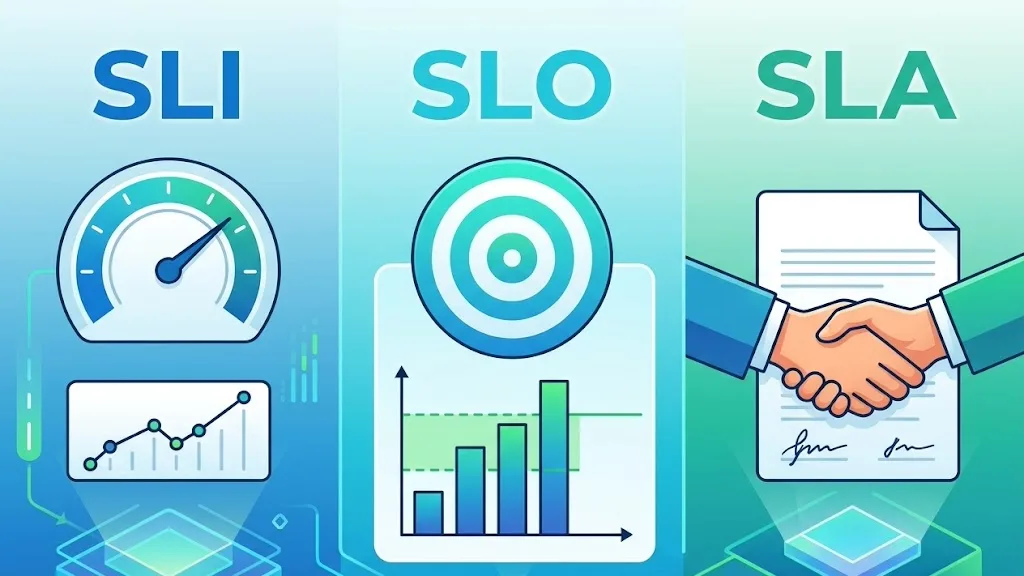
SLI, SLO, and SLA are three different things and mixing them up is expensive. Here's what each one actually measures, how they nest together, and how to pick numbers you can defend.

Twelve infrastructure monitoring tools compared on agent footprint, OS coverage, real pricing at 5/50/500 hosts, and — honestly — what each one won't help you with.